The Linguistic Translation Layer
Before a large language model can reason, summarize, or converse, it must perform an act of transformation. Computers cannot interpret words, punctuation, or grammar directly. Instead, they process raw numerical vectors. The bridge between the richness of human expression and the mathematical certainty of digital hardware is the tokenizer.
Many beginners assume that artificial intelligence treats each word as a single discrete item, much like an encyclopedia entries index. Others imagine that models inspect text letter by letter, sounding out phrases like an early reader. In truth, language models use a hybrid middle ground known as subword tokenization.
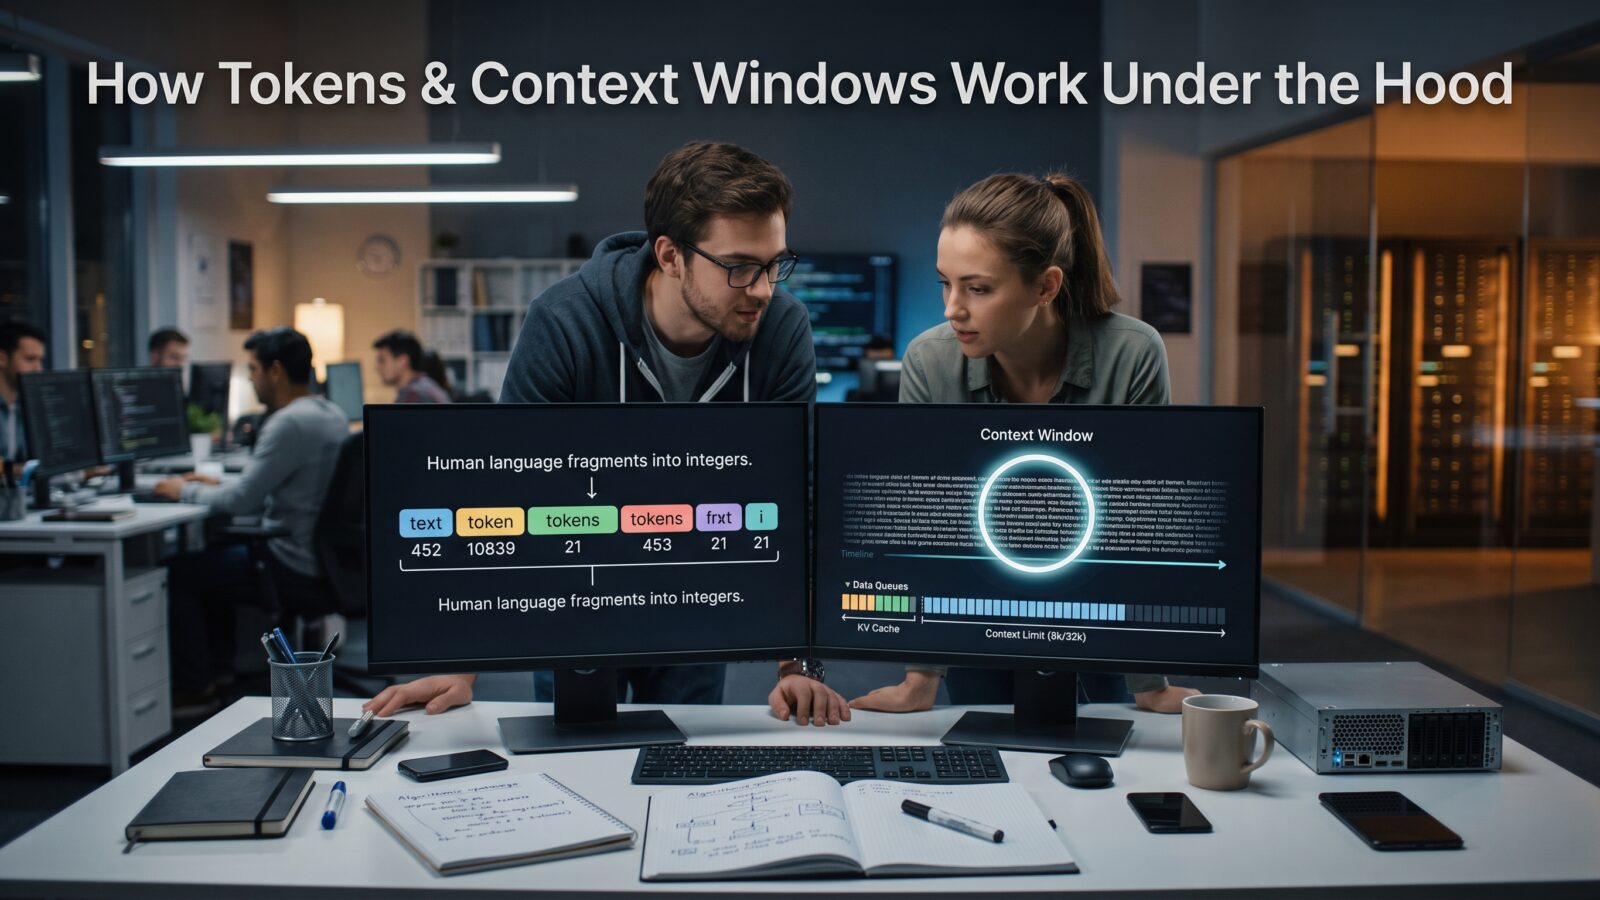
The most widely adopted framework for this process is Byte Pair Encoding. Rather than storing millions of unique whole words—which would create bloated dictionaries and fail every time a user invents a typo or a new portmanteau—the tokenizer builds a finite vocabulary of fragments. Common words like “the,” “apple,” or “system” receive their own dedicated numerical identifiers. Less common words are assembled from frequent chunks. For example, a specialized term like “electromagnetism” might be sliced into four separate pieces: “electro,” “magnet,” “is,” and “m.”
Because these fragments vary in length depending on how frequently they appear in the model’s training text, a token does not map cleanly to a standard English word. As a practical baseline, one thousand tokens typically capture roughly seven hundred and fifty words of standard English text. However, when processing non-English languages, mathematical formulas, or dense technical documentation, the fragmentation rate escalates, requiring more numerical tokens to communicate the same volume of ideas.
The Anatomy of the Context Window
Once text is converted into a sequence of numeric identifiers, it enters the context window. Think of the context window as the active working memory of the language model. Unlike humans, who rely on continuous long-term neural pathways and instinctual memory, a standard language model is inherently stateless between separate requests. It retains no lingering thoughts from previous sessions. Every time you submit a question, the model must ingest the entire conversation history from the very first greeting to the latest prompt.
The context window defines the hard boundary of that intake. If a model features a context window of thirty-two thousand tokens, that figure represents the absolute ceiling of information the model can inspect simultaneously. This budget is shared between two competing halves:
- The Input Context: Your instructions, system personas, retrieved reference documents, and preceding back-and-forth dialogue.
- The Output Generation: The new tokens the model generates in response.
If the combined sum of the background context and the requested answer exceeds the window, the architecture reaches a physical wall. Earlier sections of the conversation must be pruned, summarized, or omitted entirely.
The Hidden Bottleneck: Quadratic Attention
Why can’t engineers simply expand context windows to billions of tokens without limit? The answer lies in the fundamental mathematics of the transformer architecture: self-attention.
When a model processes a sequence of tokens, it does not evaluate them in isolation. Instead, every single token in the context must calculate an attention score relative to every other token in that same sequence. If you input ten tokens, the model must compute roughly one hundred comparative relationships. If you supply one thousand tokens, it must evaluate one million relationships.
This creates a quadratic scaling curve. Every time you double the length of the context window, the computational workload and memory pressure do not double—they quadruple.
Token Sequence Length: 1,000 ──► Computational Pairs: 1,000,000
Token Sequence Length: 2,000 ──► Computational Pairs: 4,000,000
Token Sequence Length: 10,000 ──► Computational Pairs: 100,000,000
To maintain high generation speeds, modern inference engines store these token relationships in high-speed hardware memory known as the Key-Value (KV) cache. As the context expands, the KV cache consumes massive amounts of video memory just preserving the historical records of the conversation. When models boast context windows spanning hundreds of thousands of tokens, they achieve this feat through specialized architectural compressions and memory-sharing techniques, yet the underlying economic and physical cost of long contexts remains significant.
Navigating the Lost in the Middle Phenomenon
A massive context window does not automatically guarantee perfect comprehension. Researchers have documented an innate cognitive bias in large language models known as the “lost in the middle” effect.
Because models process sequential tokens through multi-layer attention heads, they tend to pay the highest degree of attention to information situated at the extreme beginning of the prompt (the primacy bias) and at the very end of the prompt (the recency bias). Critical data points, facts, or instructions buried squarely in the middle third of an enormous prompt are disproportionately overlooked or hallucinated away.
Mastering tokens and context windows requires treating context not as an infinite trash bin, but as premium real estate. By understanding the boundaries of subword fragmentation, the quadratic reality of attention memory, and the positional tendencies of transformer architectures, architects can design prompts and pipelines that maximize clarity while keeping infrastructure costs disciplined.
